


[ARCHIVED THREAD] - FramePack - Generate AI videos from images using your computer's GPU (Now ComfyUI Megathread!) (Page 9 of 17)
Nice! Post-apocalyptic mechanic |

|
Quoted: Hmmmm I have a spare 3070 laying around, but I suspect that stuff would over-heat if I cram it into my case. The helper GPU doesn’t need to run at sustained load any longer than it takes to load the models. Then the 5090 takes over and the 3090 core goes back to idle and it essentially serves as a VRAM pack animal running at 30w. Also, by plugging the monitor into the helper GPU, you free up about 2gb vram on the 5090. |
|
I've been plugging my monitor into the mobo; using the on-board cpu graphics. Just to save a little vram on occasion... As far as a second gpu goes, it isn't so much that it is getting warm, but that it would block the intake of cool air into my (using a new fp32 T5 text encoder model)  Welcome to Arf GD |


|
Quoted: I've been plugging my monitor into the mobo; using the on-board cpu graphics. Just to save a little vram on occasion... As far as a second gpu goes, it isn't so much that it is getting warm, but that it would block the intake of cool air into my  https://www.youtube.com/watch?v=hrXIH19En2U (using a new fp32 T5 text encoder model) https://www.youtube.com/watch?v=ZTR1AtpNH5g https://www.youtube.com/watch?v=4EzqD5LR6lcCan you put your 5090 on the lower slot? |
|
IIRC, the upper one is the only gen5 pciex16 slot Which reminds me- I need to remove the nvme out of the m.2-2 slot. It is nerfing the gpu bandwidth to x8 This seems to do a good job, btw- Wan2.1 prompt generator  and that was that |

|
Friendly reminder that these are meant to be viewed in 1440p. Smack that gear icon and make it so.  Field Day 2025 was a blast |


|
Thats pretty damn cool. I like 2nd one best |
Testing a new WAN text to video workflow ComfyUI T2V Test 1  Failed To Load Title |

|
Is that 100% AI or did it start with a photo and video clip to animate it? |
|
Yeah that looks good. I’ve been traveling since Wednesday and can’t wait to try some new unlimited travel workflows when I get back tomorrow. |

|
As per usual, this was made with Wan2.1 image2video. Differently this time, a locally-installed LLM (Gemma3 27B) analyzed the picture, and I used its description as the prompt. That light reflection at the top of the pic didn't do it any favors. |

Retro anime-style text-to-video workflow. It comes with some naughty NSFW loras that are disabled by default  https://civitai.com/models/1671285/retro-90s-anime-golden-boy-style-lora-wan-14b-t2v-i2v?modelVersionId=1963359  
|

|
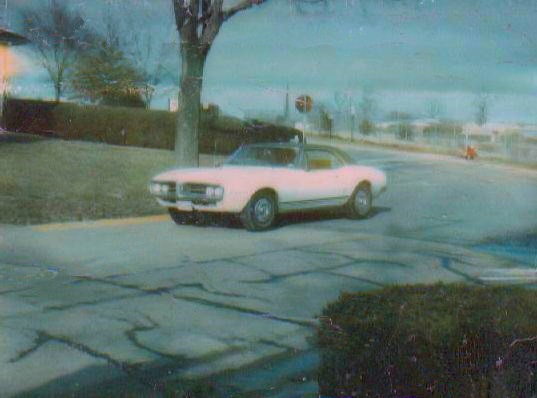
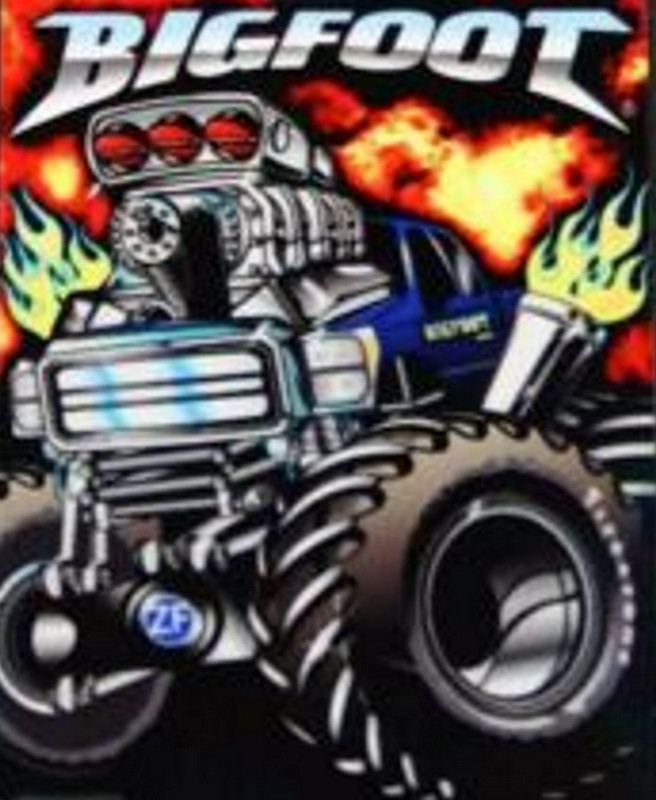
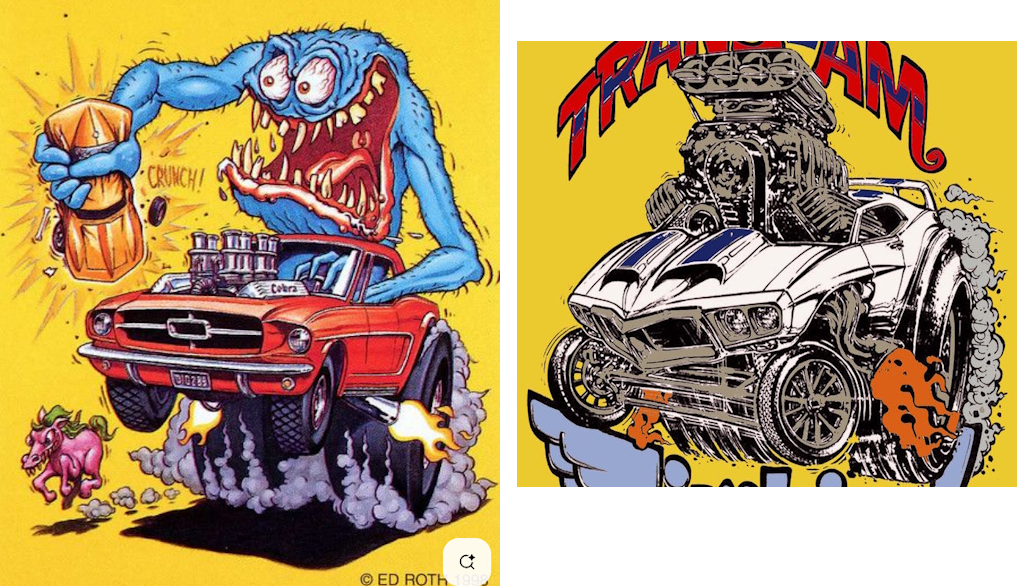
Quoted: Would someone try to take my car; https://i.postimg.cc/qqRMHVbX/67-Firebird-1.jpg https://i.postimg.cc/T1CKST7M/AI-67-Firebird-Burnout.gif ...and try to make it realistically doing Ed Roth style stuff? Something like this Bigfoot pic; https://i.postimg.cc/qRTDZQ06/Bigfoot_Phone_Cover.jpg Just the car, but driving and shooting flames like these; https://i.postimg.cc/5jcMKvy0/Ed-Roth-Mustang.png  
|


Original Buffalo Dance video from 1894: Buffalo Dance AI Upscaled. I cut the original video into 4 parts, upscaled each, then stitched back together. I also threw in some "fake frames" do double it from 30 to 60fps. Set to 4K in YouTube.  Buffalo Dance AI Upscaled Quoted: I need to figure out how to make a lora. Have been using Reactor for years to swap-in faces, but that works poorly when the subject is turning their head.... That's on my list of things to do. |
    My brain is too tired to come up with something amusing or creative  Verdun *Heights*  she digs me |
|
Quoted: https://i.postimg.cc/9QYjx6FH/Wan-00165.gif https://i.postimg.cc/3rFCx9RJ/Wan-00167.gif https://i.postimg.cc/d3Rjrjwv/Wan-00171.gif https://i.postimg.cc/3xbJCy8D/Wan-00001.gif My brain is too tired to come up with something amusing or creative https://www.youtube.com/watch?v=4eP70Qm8m8A https://www.youtube.com/watch?v=g3Nh48mF1QA https://www.youtube.com/watch?v=jpNVuccWMYQRetro anime style  |
I made my first LoRA (low rank adaptation) by training photos of Cristin Milioti. You can train one using photographs of any person, whether its a celebrity, yourself, family member, or deceased relative. It just takes about 20-30 minutes to resize, caption and upload the photos, then let it marinade in the trainer for a few hours. Once the LoRA model is ready, pop it into a text to image or text to video model and type the "trigger word" in the prompt, in this case "Milioti." It is an easier and more accurate way of developing consistent, repeatable characters than image to video.
|
I made a new LoRA, "Emma" Quoted: I may have to try learning that, because I still have trouble getting Framepack to follow prompts. (Even the ones generated on that prompt website). I'm going to try upgrading my PC to Win11 tonight, so if that breaks things I'll have to start over anyway. If you do exactly what he says in this video and how he says it, you can have a fully functional ComfyUI and LoRA generator. No coding required. https://www.youtube.com/watch?v=Na5BEQWFmic Quoted: I tried using Wan2.1 t2v as a text-to-image model for the first time today. It does a very good job. Perhaps even the best job. https://i.postimg.cc/bJjsn4yY/Wan-T2-I-0208.jpg https://i.postimg.cc/Bv2vJNxr/Wan-T2-I-Reactor-0211.jpg Wan and Hidream are both great for text to image. |
|
Quoted: I made a new LoRA, "Emma" https://www.ar15.com/media/mediaFiles/563643/FusionX_00064-ezgif_com-optimize-3587946.gif If you do exactly what he says in this video and how he says it, you can have a fully functional ComfyUI and LoRA generator. No coding required. https://www.youtube.com/watch?v=Na5BEQWFmic Wan and Hidream are both great for text to image. Quoted: I made a new LoRA, "Emma" https://www.ar15.com/media/mediaFiles/563643/FusionX_00064-ezgif_com-optimize-3587946.gif Quoted: I may have to try learning that, because I still have trouble getting Framepack to follow prompts. (Even the ones generated on that prompt website). I'm going to try upgrading my PC to Win11 tonight, so if that breaks things I'll have to start over anyway. If you do exactly what he says in this video and how he says it, you can have a fully functional ComfyUI and LoRA generator. No coding required. https://www.youtube.com/watch?v=Na5BEQWFmic Quoted: I tried using Wan2.1 t2v as a text-to-image model for the first time today. It does a very good job. Perhaps even the best job. https://i.postimg.cc/bJjsn4yY/Wan-T2-I-0208.jpg https://i.postimg.cc/Bv2vJNxr/Wan-T2-I-Reactor-0211.jpg Wan and Hidream are both great for text to image. So is that a completely AI generated female making a sandwich, or one from a photo or video that's re-0animated to be making a sammich? I guess I'm confused on what the things are, especially a LoRa (which I think is an artificial human "image" that can be made to do any number of things in a text to video sort of environment. I know of LoRa as a slow speed RF communication method for micro-controllers.  If she's imaginary, may as well give her nice C cups or so. 
|
|
Quoted: So is that a completely AI generated female making a sandwich, or one from a photo or video that's re-0animated to be making a sammich? I guess I'm confused on what the things are, especially a LoRa (which I think is an artificial human "image" that can be made to do any number of things in a text to video sort of environment. I know of LoRa as a slow speed RF communication method for micro-controllers. If she's imaginary, may as well give her nice C cups or so. Quoted: Quoted: I made a new LoRA, "Emma" https://www.ar15.com/media/mediaFiles/563643/FusionX_00064-ezgif_com-optimize-3587946.gif Quoted: I may have to try learning that, because I still have trouble getting Framepack to follow prompts. (Even the ones generated on that prompt website). I'm going to try upgrading my PC to Win11 tonight, so if that breaks things I'll have to start over anyway. If you do exactly what he says in this video and how he says it, you can have a fully functional ComfyUI and LoRA generator. No coding required. https://www.youtube.com/watch?v=Na5BEQWFmic Quoted: I tried using Wan2.1 t2v as a text-to-image model for the first time today. It does a very good job. Perhaps even the best job. https://i.postimg.cc/bJjsn4yY/Wan-T2-I-0208.jpg https://i.postimg.cc/Bv2vJNxr/Wan-T2-I-Reactor-0211.jpg Wan and Hidream are both great for text to image. So is that a completely AI generated female making a sandwich, or one from a photo or video that's re-0animated to be making a sammich? I guess I'm confused on what the things are, especially a LoRa (which I think is an artificial human "image" that can be made to do any number of things in a text to video sort of environment. I know of LoRa as a slow speed RF communication method for micro-controllers. If she's imaginary, may as well give her nice C cups or so. She is a character model trained on my GPU using photos. I load the LoRA model into my ComfyUI text to video or text to image workflow and she does whatever I say in the prompt. No further images needed. Give me some prompts and I can generate an image or video. I’m still figuring out this training thing, but this particular LoRA doesn’t seem to shut up 
|
|
Quoted: She is a character model trained on my GPU using photos. I load the LoRA model into my ComfyUI text to video or text to image workflow and she does whatever I say in the prompt. No further images needed. Give me some prompts and I can generate an image or video. I’m still figuring out this training thing, but this particular LoRA doesn’t seem to shut up https://www.ar15.com/media/mediaFiles/563643/FusionX_00109-ezgif_com-optimize-3587959.gif Quoted: Quoted: Quoted: I made a new LoRA, "Emma" https://www.ar15.com/media/mediaFiles/563643/FusionX_00064-ezgif_com-optimize-3587946.gif Quoted: I may have to try learning that, because I still have trouble getting Framepack to follow prompts. (Even the ones generated on that prompt website). I'm going to try upgrading my PC to Win11 tonight, so if that breaks things I'll have to start over anyway. If you do exactly what he says in this video and how he says it, you can have a fully functional ComfyUI and LoRA generator. No coding required. https://www.youtube.com/watch?v=Na5BEQWFmic Quoted: I tried using Wan2.1 t2v as a text-to-image model for the first time today. It does a very good job. Perhaps even the best job. https://i.postimg.cc/bJjsn4yY/Wan-T2-I-0208.jpg https://i.postimg.cc/Bv2vJNxr/Wan-T2-I-Reactor-0211.jpg Wan and Hidream are both great for text to image. So is that a completely AI generated female making a sandwich, or one from a photo or video that's re-0animated to be making a sammich? I guess I'm confused on what the things are, especially a LoRa (which I think is an artificial human "image" that can be made to do any number of things in a text to video sort of environment. I know of LoRa as a slow speed RF communication method for micro-controllers. If she's imaginary, may as well give her nice C cups or so. She is a character model trained on my GPU using photos. I load the LoRA model into my ComfyUI text to video or text to image workflow and she does whatever I say in the prompt. No further images needed. Give me some prompts and I can generate an image or video. I’m still figuring out this training thing, but this particular LoRA doesn’t seem to shut up https://www.ar15.com/media/mediaFiles/563643/FusionX_00109-ezgif_com-optimize-3587959.gif Ok, so a still photo with her in a pose would work as an accurate female model for a figure drawing? Those are Normally copyrighted and protected but for people learning art I think this could open up a lot of new material to practice/learn from instead of paying $50/photo just to practice pencil drawing accurately getting the anatomy of muscles correct and things like that. I suppose chaining from there, it's going to shake the foundations of the pr0n industries as well. |

|
Just bought a rog zephyrus, ryzen 9ai hx, 5070ti 32gb i think. Please I'm sure it's shit or something, but I know nothing and wanted a laptop. My ai sidekick recommended it, for what I need. But I can access this use with my lt now? Do you guys have coding knowledge to use this? I'm thinking of learning python. But ai said you're maybe using light coding? |
|
Quoted: Just bought a rog zephyrus, ryzen 9ai hx, 5070ti 32gb i think. Please I'm sure it's shit or something, but I know nothing and wanted a laptop. My ai sidekick recommended it, for what I need. But I can access this use with my lt now? Do you guys have coding knowledge to use this? I'm thinking of learning python. But ai said you're maybe using light coding? You have 16 GB VRAM which more than enough to join the party. If you run out or VRAM, you increase the number of blocks to swap to the DRAM, run a lower floating point format (FP8 vs FP16) or lower the resolution. The majority of people on the AI Discords have 4 to 16GB vram and are making impressive stuff, even with as little as 4GB. I’d suggest upgrading the DRAM to 96GB, which is easy on a laptop. You’ll also need more storage than 1TB, but that’s also easy to upgrade. You don’t need to code to set up ComfyUI or the FramePack standalone. The link to FramePack is in the OP. For ComfyUI, just follow the instructions in this video: https://youtu.be/Na5BEQWFmic?si=zrZymT9V8p-NYsf- |
|
Quoted: You have 16 GB VRAM which more than enough to join the party. If you run out or VRAM, you increase the number of blocks to swap to the DRAM, run a lower floating point format (FP8 vs FP16) or lower the resolution. The majority of people on the AI Discords have 4 to 16GB vram and are making impressive stuff, even with as little as 4GB. I'd suggest upgrading the DRAM to 96GB, which is easy on a laptop. You'll also need more storage than 1TB, but that's also easy to upgrade. You don't need to code to set up ComfyUI or the FramePack standalone. The link to FramePack is in the OP. For ComfyUI, just follow the instructions in this video: https://youtu.be/Na5BEQWFmic?si=zrZymT9V8p-NYsf- Quoted: Quoted: Just bought a rog zephyrus, ryzen 9ai hx, 5070ti 32gb i think. Please I'm sure it's shit or something, but I know nothing and wanted a laptop. My ai sidekick recommended it, for what I need. But I can access this use with my lt now? Do you guys have coding knowledge to use this? I'm thinking of learning python. But ai said you're maybe using light coding? You have 16 GB VRAM which more than enough to join the party. If you run out or VRAM, you increase the number of blocks to swap to the DRAM, run a lower floating point format (FP8 vs FP16) or lower the resolution. The majority of people on the AI Discords have 4 to 16GB vram and are making impressive stuff, even with as little as 4GB. I'd suggest upgrading the DRAM to 96GB, which is easy on a laptop. You'll also need more storage than 1TB, but that's also easy to upgrade. You don't need to code to set up ComfyUI or the FramePack standalone. The link to FramePack is in the OP. For ComfyUI, just follow the instructions in this video: https://youtu.be/Na5BEQWFmic?si=zrZymT9V8p-NYsf- Thank you, I'll see if I can figure it out. My ai assistant hallucinated, told me 8gb vram, that liar. Or wait, now it's reversed back to 8gb with pretty strong argument. Either way it's above 6gb from the op. Glad it can handle this, glad the thread popped up to remind me. ETA now *12gb final answer, believe her this time, but down votes are coming for some of her answers ??. |
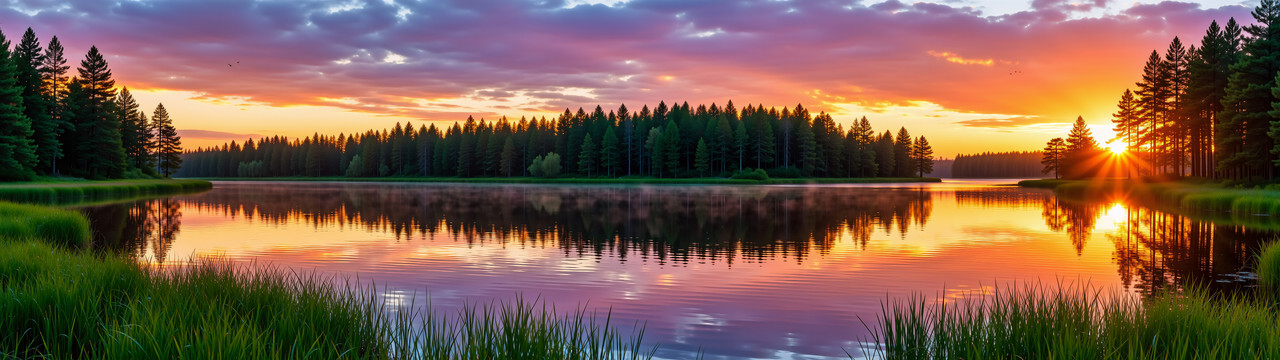 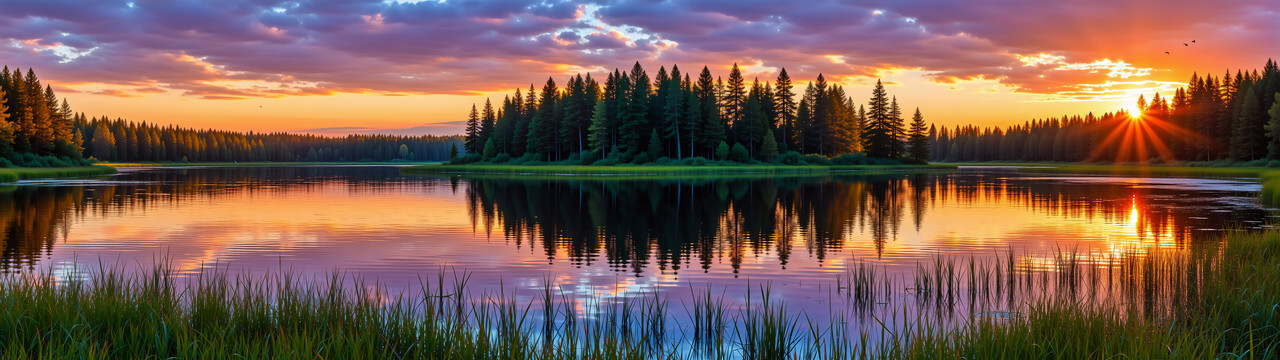 "The camera glides slowly over a tranquil forest lake at golden hour, capturing vivid reflections of the fiery orange, pink, and purple sunset in the still water. Pine trees on the right glow as sunbeams pierce through them. The camera gently orbits above the lake, dipping low to skim the mirror-like surface, then rising to reveal the endless sky. A warm breeze rustles the grass and ripples the water slightly. Birds fly across the sunset in the distance. Ultra high quality, 4K, cinematic, natural movement, vibrant colors, peaceful yet majestic atmosphere" Used a video prompt for t2i. First gen tonight. I like it.  
|
 First Date The sword kept on glitching. Entirely AI using a character I made. First step was text-to-image using Hunyuan, then image-to-video using WanFusion. All locally generated. The background movement made the first attempts not so good at 60fps, so bumped it up to 180. |
|
Quoted: https://www.youtube.com/watch?v=4iVqXVDO7LgThe sword kept on glitching. Entirely AI using a character I made. First step was text-to-image using Hunyuan, then image-to-video using WanFusion. All locally generated. That's amazing. You have ea video clip of somebody that doesn't and hasn't existed before. Even 10 years ago it was assumed creative3 process would be needed to create characters from some base outline actor, similar to Deep Fakes or in the other direction with Davy Tentacle Face in Pirates of Caribbean and others where motion tracking was used for everything linked to facial muscles because of number and being too hard to create without hitting uncanny valley. |
|
Quoted: https://www.youtube.com/watch?v=4iVqXVDO7LgThe sword kept on glitching. Entirely AI using a character I made. First step was text-to-image using Hunyuan, then image-to-video using WanFusion. All locally generated. Have you made a LoRA out of her yet? Then you can summon her with text to video. |
|
No. Every time I attempt to do so, even including the instructions you posted, I get nothing but error messages. Really want to do so. The face will glitch badly if turned more than perhaps 45 degrees in any direction.  Second date? Even at 150fps ^, the background was a little choppy. |
|
Quoted: No. Every time I attempt to do so, even including the instructions you posted, I get nothing but error messages. Really want to do so. The face will glitch badly if turned more than perhaps 45 degrees in any direction. They're pretty awesome. If you send me the data set, I can make you one. The data set is 20-30 images, each resized 768x768, along with a caption for each image that describes everything in detail (LLMs can help with this). 
|
|
I hope to do something along these lines soon. My new case will be here in a few days, and then my son will help me with transferring parts and then upgrade to Win11. Then I'll put the better programs on, and hope that I can learn them. I'm surprised that the one above won't turn a face, because FramePack has been creating and turning them for me. From this;  To this;  |
|
Quoted: I hope to do something along these lines soon. My new case will be here in a few days, and then my son will help me with transferring parts and then upgrade to Win11. Then I'll put the better programs on, and hope that I can learn them. I'm surprised that the one above won't turn a face, because FramePack has been creating and turning them for me. From this; https://i.postimg.cc/DwY6t0C4/2000s-Linda-Church-1.jpg To this; https://i.postimg.cc/WpM9h24x/2025-5-22-AI-1st.gif The one GySgt_D and I are using (Wan 2.1) has the same problem as Framepack in that it changes the face. A LoRA solves this problem because it is a digital model of whoever you want it to be, trained with either images, or a combination of images and video. You can then summon them into your scene by entering their name into the prompt. You get the same person every time and it doesn’t change their physical characteristics.  
|